
inference.ai provides a single platform to deploy agents, route model requests, access wholesale GPU compute, and learn implementation skills.
What it is
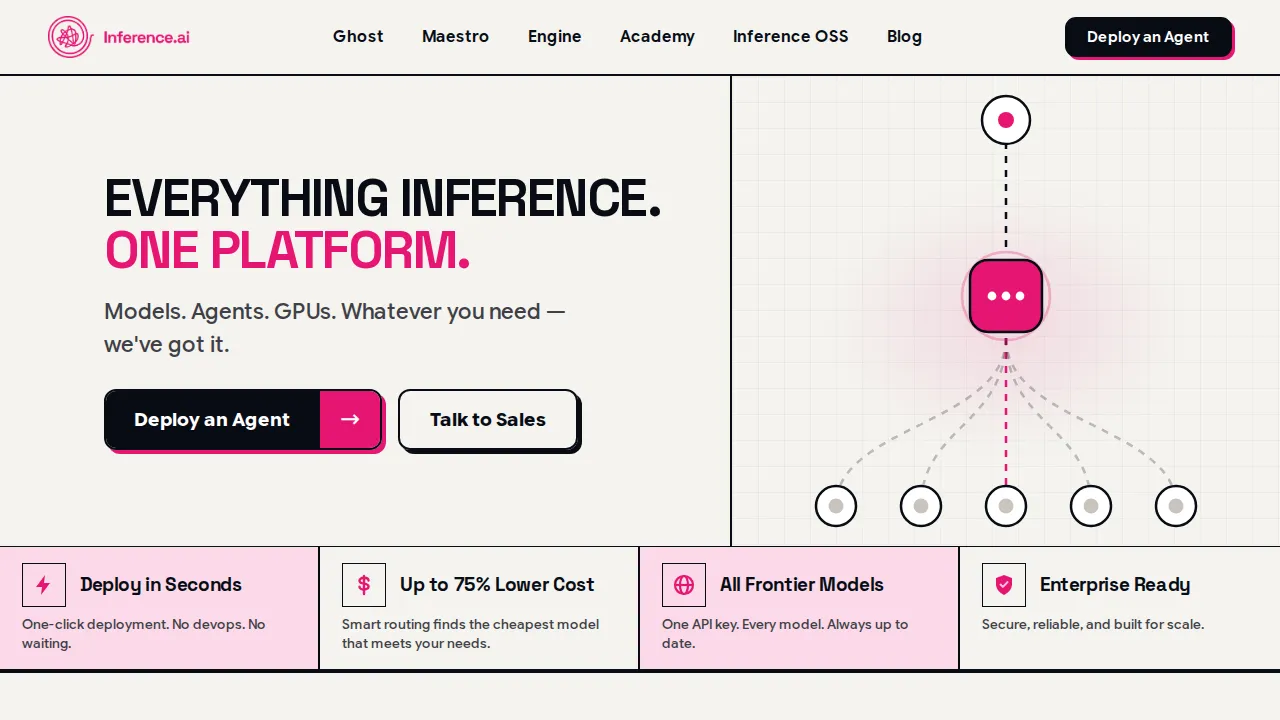
inference.ai is a comprehensive infrastructure provider that unifies frontier models, intelligent routing, bare-metal GPUs, and educational resources into a single operational stack. The platform serves developers and organizations looking to manage workloads, minimize computing expenses, and deploy autonomous workflows without managing complex infrastructure.
Key features
- One-click agent deployment with pre-configured persistent virtual machines ready in seconds
- Smart routing layer that selects the most cost-effective model for every request based on speed, budget, and quality constraints
- Wholesale compute access ranging from RTX 4090s up to Blackwell B300s with InfiniBand clustering capabilities
- Single API key providing access to updated frontier models including DeepSeek, Qwen, and Kimi
- Interactive training through Academy where users build on production infrastructure guided by coaching sessions
Who it's for
inference.ai suits developers, engineers, and enterprise teams scaling machine learning operations, managing multiple model endpoints, or seeking cost-efficient GPU rentals for heavy training workloads.
Pricing
Check the official website for current pricing.
Use cases
- Deploy autonomous agents
- Route queries to cost-effective models
Categories:
Similar to inference.ai
More inference.ai alternatives
API for multi-model AI inference and custom agents
Pollinations.ai provides an open infrastructure for connecting models, custom agents, and hosted tools through a single unified API endpoint.

